Built with Muse Publish a workflow
Social · Local & open models

Muse for local & open models.

Muse Glimmer and other open weights running on people's own hardware.

37 posts · page 1 of 2

Zuckerberg opens Muse Glimmer weights

Mark Zuckerberg@finkd · 10 Aug

Today we're also opening the weights for Muse Glimmer, a great 30B parameter dense model that can run locally. Soon we'll also release the weights for Muse Spark 1.2, our latest foundation model. Meta is a strong supporter of open source and I'm proud of these releases. Congrats
Glimmer on 24GB VRAM

Alexandr Wang@alexandr_wang · 10 Aug

1/ big announcement today: we will be releasing an open weight version of muse spark 1.2 soon. we also are releasing muse glimmer, a 30B agentic model with open weights under apache 2.0. muse glimmer can run on 24GB of VRAM without losing agentic reliability. 🧵

Unsloth GGUFs and guide for Muse Glimmer

Unsloth AI@UnslothAI · 10 Aug

Meta releases Muse Glimmer, a new 30B open model that runs on 18GB RAM. Muse Glimmer is Apache 2.0 licensed, supports vision and is the strongest agentic model for its size. Run and train the model via Unsloth. GGUF: https://t.co/AoVKEDmcxI Guide: https://t.co/uBwdINO0PS https://t.co/wCYQEAuQ7H

2-bit Glimmer GGUF: 100+ tool calls on 14GB RAM

Unsloth AI@UnslothAI · 10 Aug

2-bit Muse Glimmer GGUF managed to call 100+ tools on just 14GB RAM. 🔥 Muse Glimmer did a complete repo bug hunt for 5 mins nonstop with: evidence, repro, fix, tests and a PR writeup. Run and train it in Unsloth. GitHub repo: https://t.co/aZWYAtakBP https://t.co/ELquwFTeNk

Muse Glimmer 30B in LM Studio

LM Studio@lmstudio · 10 Aug

Muse Glimmer 30B is live in LM Studio! It's a new open source model from Meta. Apache 2.0 license, fit right on your laptop. It is the strongest model of its size class we've tested.

Muse Glimmer on Ollama's MLX engine

ollama@ollama · 10 Aug

Muse Glimmer is now available to run with Ollama. Available today via Ollama’s MLX engine with state-of-the-art-performance on Apple Silicon, Muse Glimmer can power Claude Code, Codex, and more always-on local agent workflows natively using Ollama. Additional support and

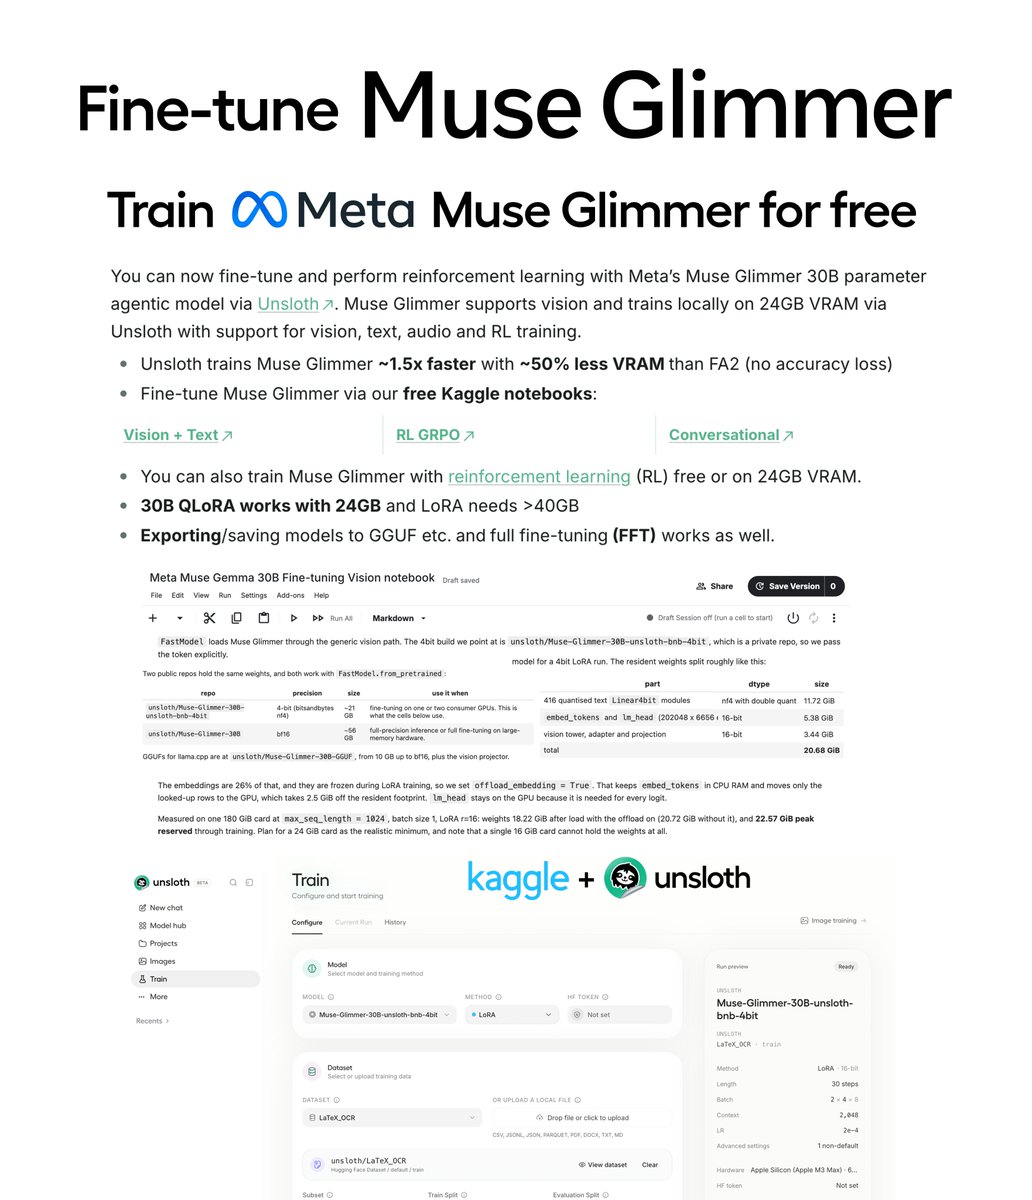
Free Muse Glimmer fine-tuning notebook

Unsloth AI@UnslothAI · 13 Aug

You can now fine-tune Meta Muse Glimmer 30B for free! 🔥 Our free notebook also supports GRPO RL training. Unsloth trains Muse Glimmer 1.5× faster with 50% less VRAM vs FA2 setups. Train locally with 24GB VRAM. Guide: https://t.co/gEykiA7ygY Notebooks: https://t.co/LX1RWMo7V5 https://t.co/au5xaspsg9

Muse Spark 1.2 robot navigation

AI at Meta@AIatMeta · 20 Aug

Muse Spark 1.2 supports a broad range of multimodal tasks, from turning visuals into working code to translating perception into physical action. It also brings robust audio-visual understanding to enable video-heavy workflows common in real-world enterprise use. Today, we’re https://t.co/ryDgr78s2p

How Glimmer fits on consumer hardware

AI at Meta@AIatMeta · 10 Aug

For a local agent to be practical, generation latency must be low enough to maintain workflow continuity. To run Muse Glimmer on consumer hardware without degrading quality, we used quantization to shrink the language model to under 20GB and a lightweight DFlash drafter model to https://t.co/Qg170bgNPS

Glimmer builds a Home Assistant dashboard

AI at Meta@AIatMeta · 10 Aug

Muse Glimmer can complete multi-step agentic tasks end-to-end from a single natural language prompt. In this demo, it autonomously discovers a local Home Assistant instance via network tool calls, queries device APIs, writes a responsive HTML/CSS/JS dashboard from scratch, and https://t.co/p68V2srISM

Day-0 Glimmer support in transformers

merve@mervenoyann · 10 Aug

Meta released Muse Glimmer 30B: multimodal model for your Claw/Pi setups 🔥 we tested and fine-tuned the model for you, and shipped day-0 support in transformers and llama.cpp, including DFlash for 2-4x speed-ups 🥵 read our blog https://t.co/u04QfXk1m2

Glimmer bench on a single RTX 4090

Alok@analogalok · 10 Aug

Muse Glimmer, A 30B parameter dense model swallowing a 130,000 token context window using only 19.3 GB of VRAM (extreme efficiency). No KV cache quantization required. I just benched the new Muse Glimmer 30B (dense) on a single RTX 4090. We are pulling 3,100+ t/s prefill and 75 https://t.co/ZZla0FM39S

Local credit card statement analysis with Glimmer

ollama@ollama · 13 Aug

Using @AIatMeta's Muse Glimmer all locally to process personal monthly credit card statements. Your data belongs to you! Try different agent tasks using your favorite apps / harnesses with Ollama. https://t.co/LDeCaCZHOH

Day-0 vLLM support for Muse Glimmer

vLLM@vllm_project · 10 Aug

@Meta is back in open source. Excited to announce Day-0 vLLM support for Muse Glimmer 30B, the first open-weights model from Meta Superintelligence Labs — which ships under Apache 2.0!!! 30B dense, 128K+ context, multimodal, built for local agents. Capable enough for

Muse Glimmer GGUF on Hugging Face

Simon Willison@simonw · 10 Aug

Muse Glimmer, the new 30B model, is available on Hugging Face right now - here's the GGUF version: https://t.co/z4y28kbjlu

Glimmer at 208 tok/s average on one RTX 5090

Kyle Hessling@KyleHessling1 · 10 Aug

First impressions on Muse Glimmer! It's incredibly fast for a dense model, currently running an average of 208tps with a max of 274tps on a single 5090 with their DFLASH config. Comparatively, though, both using Open Code, Qwopus Coder (with thinking off) produced a much https://t.co/a6uBBBmbh5

Muse Glimmer with 130k context on free Kaggle T4s

Alok@analogalok · 13 Aug

The "I don't have enough VRAM" excuse just died. I’m running Meta’s new 30B Muse Glimmer Q6_K_XL with a massive 130k context window on just 26GB VRAM FREE compute on Kaggle. Kaggle provides you free 2x Nvidia T4 GPUs. 30 hours usage each week! Yesterday, I showed you the https://t.co/wlM4J03vFW

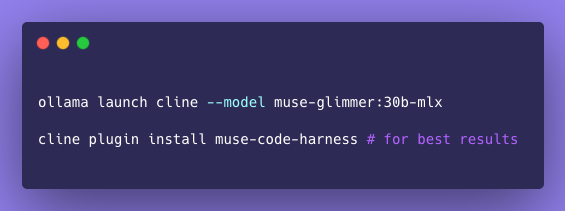
Muse Glimmer in Cline

Cline@cline · 10 Aug

The successor to Llama is here, and Meta is revitalizing focus on open weights with their new Muse Glimmer - a leading 30B param model designed for always-on local agent use, small enough to run on a Mac or PC with a single GPU. Available in Cline using Ollama now! https://t.co/0v5O0VG864

DFlash drafter speeds Glimmer up 2-4x

merve@mervenoyann · 11 Aug

Muse Glimmer 30B is shipped with DFlash drafter which speeds-up generation 2-4x at little memory cost 🔥 we support this in llama.cpp and transformers, see below how it looks like in the wild (llama webui) ⤵️ https://t.co/1gtEi9mDie

SGLang serves Glimmer at ~230 tok/s on one RTX 5090

LMSYS Org@lmsysorg · 10 Aug

@AIatMeta's Muse Glimmer (30B dense, open-weights) launches with SGLang day-0 support. We got ~230 tok/s on a single RTX 5090, with NVFP4 + DFlash on. It also works out of the box on @NVIDIAAIDev RTX Pro 6000, DGX Spark, and MLX for Mac. Speed and reliability have always been https://t.co/aGEbkLe7L5

Muse Glimmer on an M5 Max Mac

AshutoshShrivastava@ai_for_success · 10 Aug

Got Muse Glimmer 30B running locally on my Mac (M5 Max - 128 GB )and the instruction following is impressive. need to setup with opencode next Video Speed - 5X https://t.co/4u6sAxRFpH

Muse Glimmer quantizes itself

Ben Burtenshaw@ben_burtenshaw · 10 Aug

Meta is back with Muse Glimmer: a 30B open-source multimodal model built for local, agentic use. HF is shipping day-0 support and I built a few demos to see what it can do. First: we gave Glimmer tools and asked it to quantize itself. https://t.co/YmBPYVVF9P

Muse Glimmer fine-tuning tutorial on MolmoWeb

merve@mervenoyann · 12 Aug

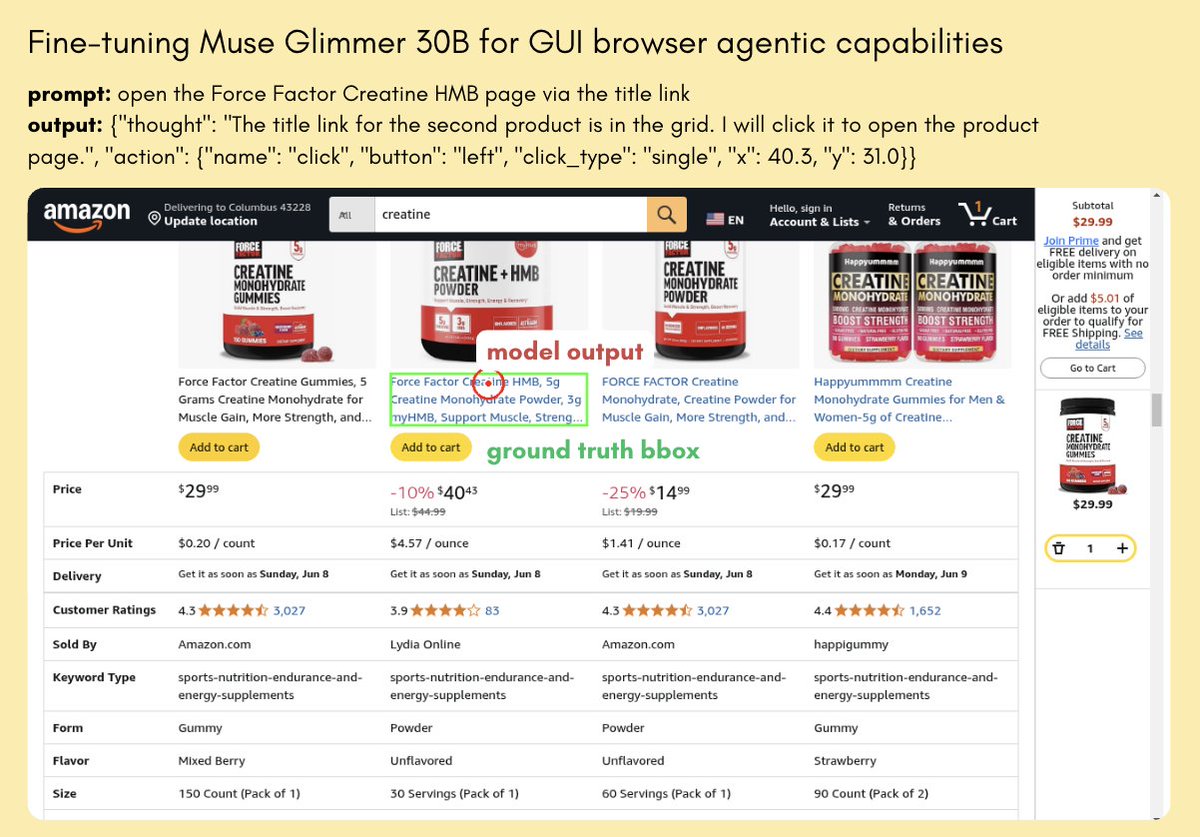
I shipped a fine-tuning tutorial for Muse Glimmer 30B on AI2's MolmoWeb dataset with TRL https://t.co/HNtd3FH5u2 > but merve, this model is sota on ScreenSpot-Pro? yes, but it doesn't work well with ambiguous prompts of MolmoWeb that are close to how you interact with computer, https://t.co/zheepNH9Ep

One-line llama serve for Glimmer with DFlash

merve@mervenoyann · 11 Aug

this is super easy to run install llama binary: curl -LsSf https://t.co/u11bzUcUoY | sh run: llama serve -hf meta-models/muse-glimmer-30b --spec-type draft-dflash -fa on --jinja please spread the word

Questions

What have people actually used Muse for when it comes to local & open models?

37 public posts describe it. Muse Glimmer and other open weights running on people's own hardware. Each card above quotes the poster or condenses their post, and links to the original.

Are these results verified?

No. Outcomes are what each poster reported. Built with Muse did not verify the savings, bookings or completions. 37 of the 37 posts are in the poster's own words; the rest are condensed summaries with a link back.

Can I try the same thing?

0 of these posts come with a prompt you can copy and adapt. Open Try the prompt on a card, paste it into Muse, and replace the bracketed parts with your own details.

How do I get Muse?

Muse is invite only in most places. Built with Muse runs a community pool of invite codes: take one, redeem it in the Muse app, then add your own for the next person.

Outcomes are what the poster reported. Built with Muse did not verify the savings, bookings, or completions. Posts with text_source tweet are the author's own words. Posts with text_source field-guide-summary are condensed from the public post by the EveryAI Muse field guide (snapshot 2026-09-14) and link back to the original. Some entries were first catalogued by shipwithmuse.live. Data updated 2026-10-09.