 Alexandr Wang@alexandr_wang · 9 Jul
Muse Spark 1.1 outperforms Opus 4.8 and Grok 4.5 on some nice out of distribution evals :)
Evals, comparisons and research findings about Muse models.
Alexandr Wang@alexandr_wang · 9 Jul
Muse Spark 1.1 outperforms Opus 4.8 and Grok 4.5 on some nice out of distribution evals :)
 Vals AI@ValsAI · 6 Aug
Muse Spark 1.2 is the first model to crack 60% on Finance Agent v2, our benchmark that gives models the job of a financial analyst. At $0.77/test it is 6.7x cheaper than the previous #1, Opus 5 ($5.12), at twice the speed. https://t.co/MrTRzfOKiu

 Arena.ai@arena · 7 Aug
Muse Spark 1.2 (xHigh) by @AIatMeta is #14 in the Code Arena: WebDev, with 1,545 pts! This is an improvement from Muse Spark 1.1 at #18. See its biggest gains by category in the post below. Congrats to the @AIatMeta team on this release! https://t.co/7wKI8oWAmx

 Deedy@deedydas · 12 Apr
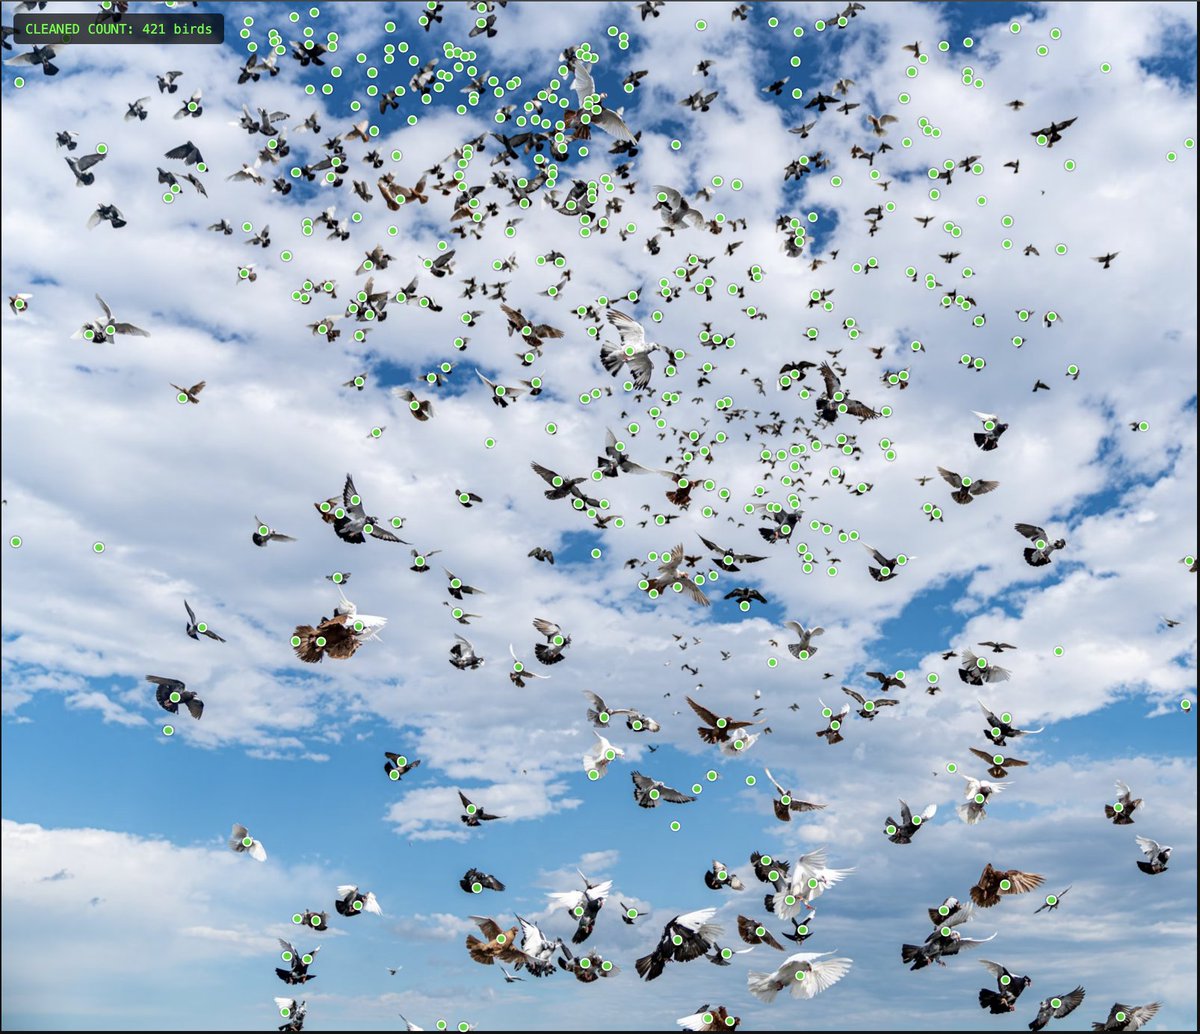
The coolest thing Meta AI's Muse Spark can do by far is counting objects! As you can tell, it's far from perfect. They call it "visual grounding" and it can count objects and do bounding boxes. I've been playing with the new model and here's what I think so far: Good stuff: – https://t.co/5lGNPNxURs
 wh@nrehiew_ · 10 Aug
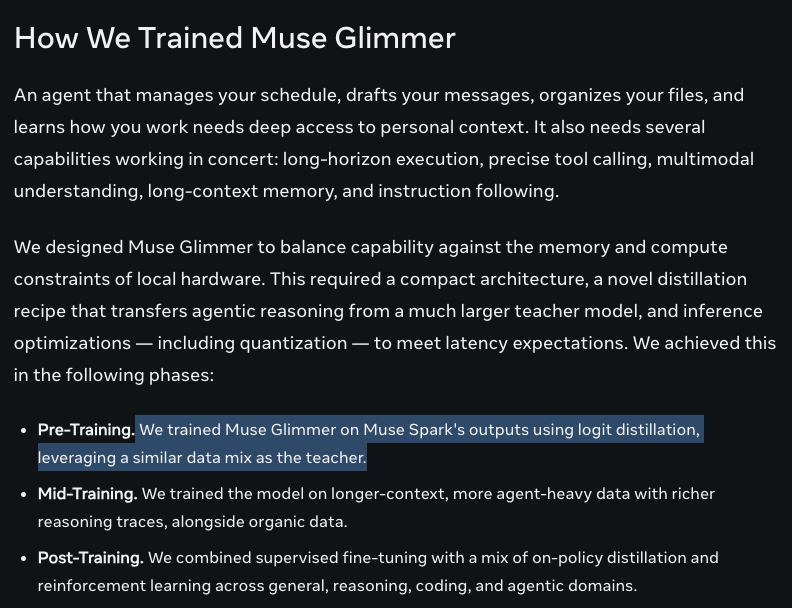
Muse Glimmer was trained directly logit distilled from Muse Spark. This means that there isn't a traditional 'base model' in that it was trained from the start on agentic traces. Super cool and haven't seen this approach in a while Welcome back GPT OSS https://t.co/WpIYrhwm6U
 Arena.ai@arena · 8 Sept
Muse Spark 1.3 Max by @AIatMeta has reshaped the Pareto frontier for Code Arena: WebDev! Meta's latest model at Max reasoning is doing something interesting on the Arena Pareto frontier: it's the only model holding down the wide price band between Qwen3.8-max ($5/MToken) and https://t.co/g3S5Jthaqx

 Evergreen Capital@evergreencap3 · 9 Apr
I tested $META's Muse Spark over the last few hours and came away net positive. 3 main takeaways: 1) Quality: It's a very good model. Not quite frontier but good. It showed comparable performance vs Opus 4.6 across web data search, PDF parsing, and general https://t.co/lYVyUnXsL4
 Arena.ai@arena · 10 Jul
Muse Spark 1.1 has entered the Code Arena: Frontend at #9! Muse Spark 1.1 reshapes the cost-performance Pareto Frontier by scoring 1541 at a blended $3.5M ($1.25 per input MToken, $4.25 per output MToken). This is frontier performance at a fraction of the price. Congrats to https://t.co/RYxc5GuRfj

 Simon Willison@simonw · 8 Apr
Pelicans for Meta's new Muse Spark models - plus I did a bit of a deep dive into the Code Interpreter and fascinating "container.visual_grounding" tools in their https://t.co/Qq1tQtgKH7 chat UI https://t.co/NIQB6ZACDC
 🚨 AI News | TestingCatalog@testingcatalog · 8 Sept
Since the Meta Muse agent isn't available to everyone, here is a quick UI walkthrough of its web version. Highlights 👀 > The animated Muse avatar is very cool! You can ask Muse to change how it looks, and it will generate the new look along with all the animations. > https://t.co/U4nIaS86sa

 J A Z I I@notjazii · 2 Sept
meta muse just mogged fable 5.1 tested fable 5.1 and muse spark 1.3 with same prompt at highest reasoning available and results came out really different > muse spark 1.3 completed task in one minute and costed almost nothing > fable 5.1 completed task in 70 minutes and costed https://t.co/qucQTTBDAf
 Arena.ai@arena · 20 Aug
Muse Spark 1.2 (xHigh) by @AIatMeta is now in Agent Arena, with a net improvement of +2.1%! Agent Arena measures models on millions of real-world, long-horizon agentic tasks. We use causal tracing methodology to measure a model's net improvement, indicating how much it improves https://t.co/b9Q0Za4RLC

 Design Arena@DesignArena · 20 Aug
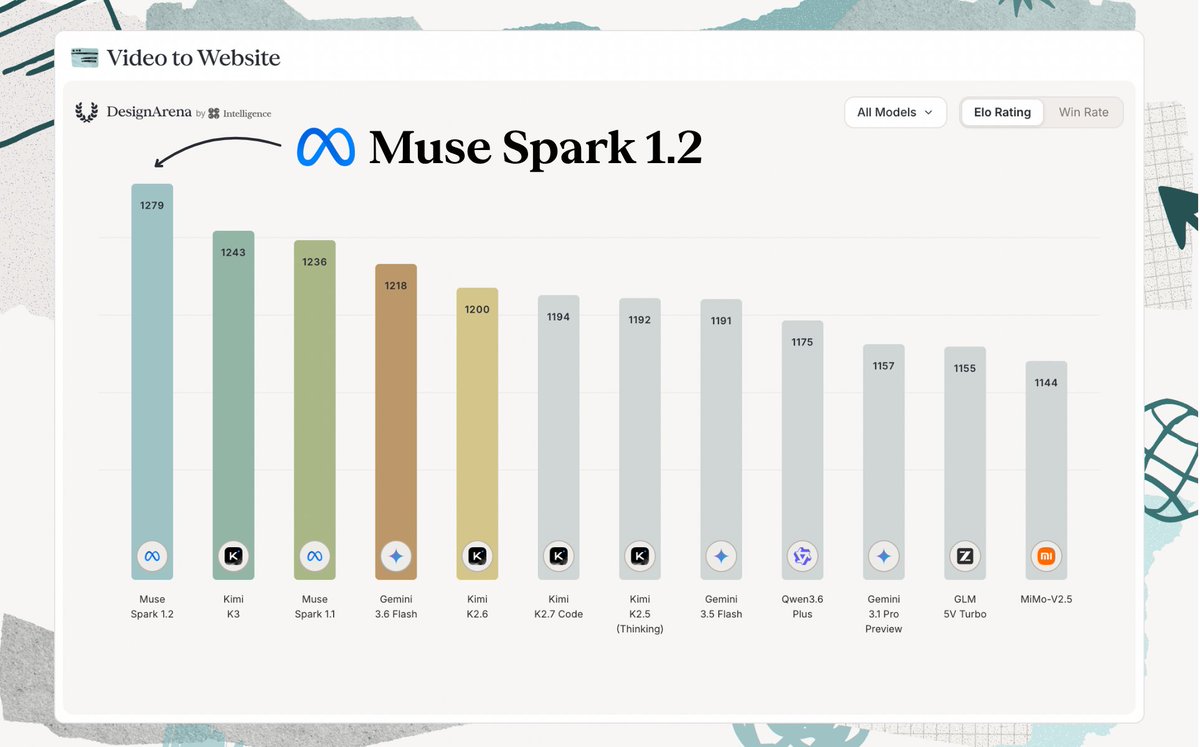
BREAKING: Muse Spark 1.2 by @AIatMeta takes 1st for Video-to-Website with an Elo rating of 1279 and impressive scores across all of our multimodal code categories. Muse Spark 1.2 also takes 2nd for Image-to-HTML with an Elo rating of 1252 and 3rd for Image-to-Frontend with Elo https://t.co/TwpJ0TPpq9


 Jason Wei@_jasonwei · 9 Jul
In addition to agents and coding, Muse Spark 1.1 is also really strong at answering health questions, a steadily growing use case for AI. On HealthBench-Pro, Muse Spark 1.1 achieves +5% better performance than Muse Spark 1.0 and beats all competitor models except Fable/Mythos. https://t.co/tx3suaTfTs

 Dan@DanDr1s · 2 Sept
Meta’s Muse Spark 1.3 just scored 62 on Artificial Analysis’ Intelligence Index. That ties Claude Fable 5, but Muse costs 8x less for input and nearly 12x less for output. It also scores above GPT-5.6 Sol, Grok 4.6, Kimi K3, and Gemini 3.8 Flash. Meta is suddenly in the top https://t.co/XkwLxJUNGD

 Trapit Bansal@TrapitBansal · 6 Aug
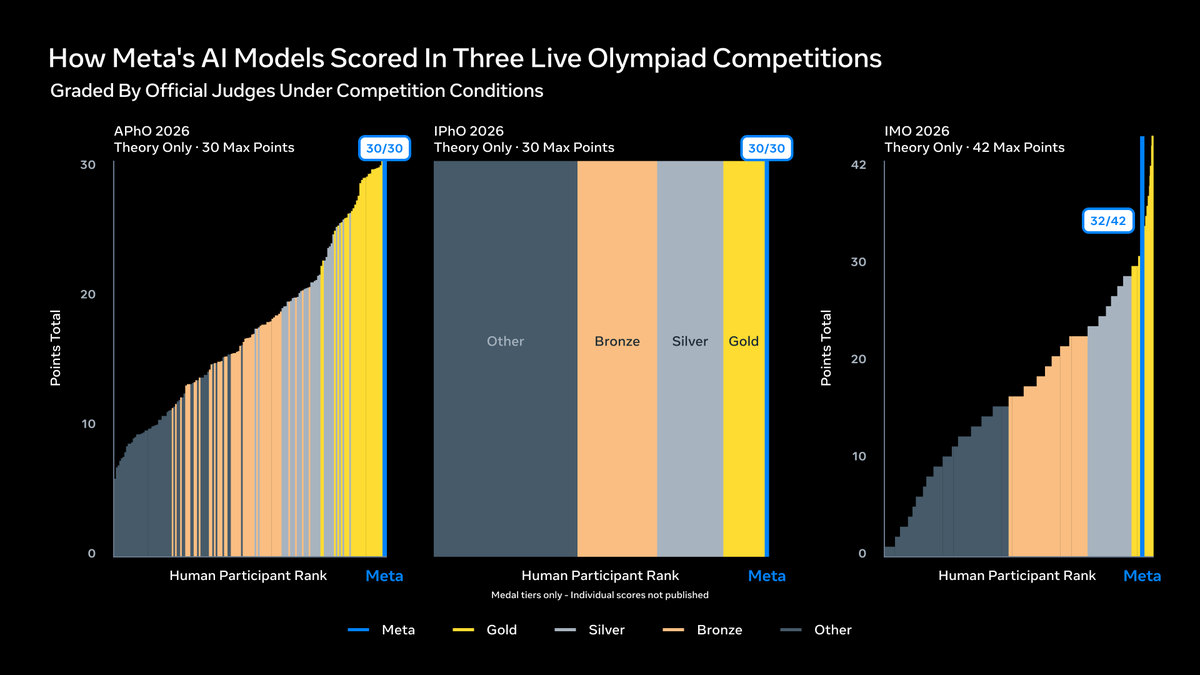
We entered Meta models in five international STEM Olympiads, as an uncontaminated eval of their reasoning capabilities. Three of these were live participations and graded officially. The models achieved gold-medal results in all five! 1/5 https://t.co/JSXrQpNMJE
 Cline@cline · 9 Jul
Muse Spark 1.1 just launched and it's their most capable coding agent model yet. On Terminal-Bench 2.1 it scores 80.0%, in the same cluster as Opus 4.8 (82.7%) and GPT 5.5 (83.4%). Use it in Cline with the Meta API!
 AI at Meta@AIatMeta · 9 Jul
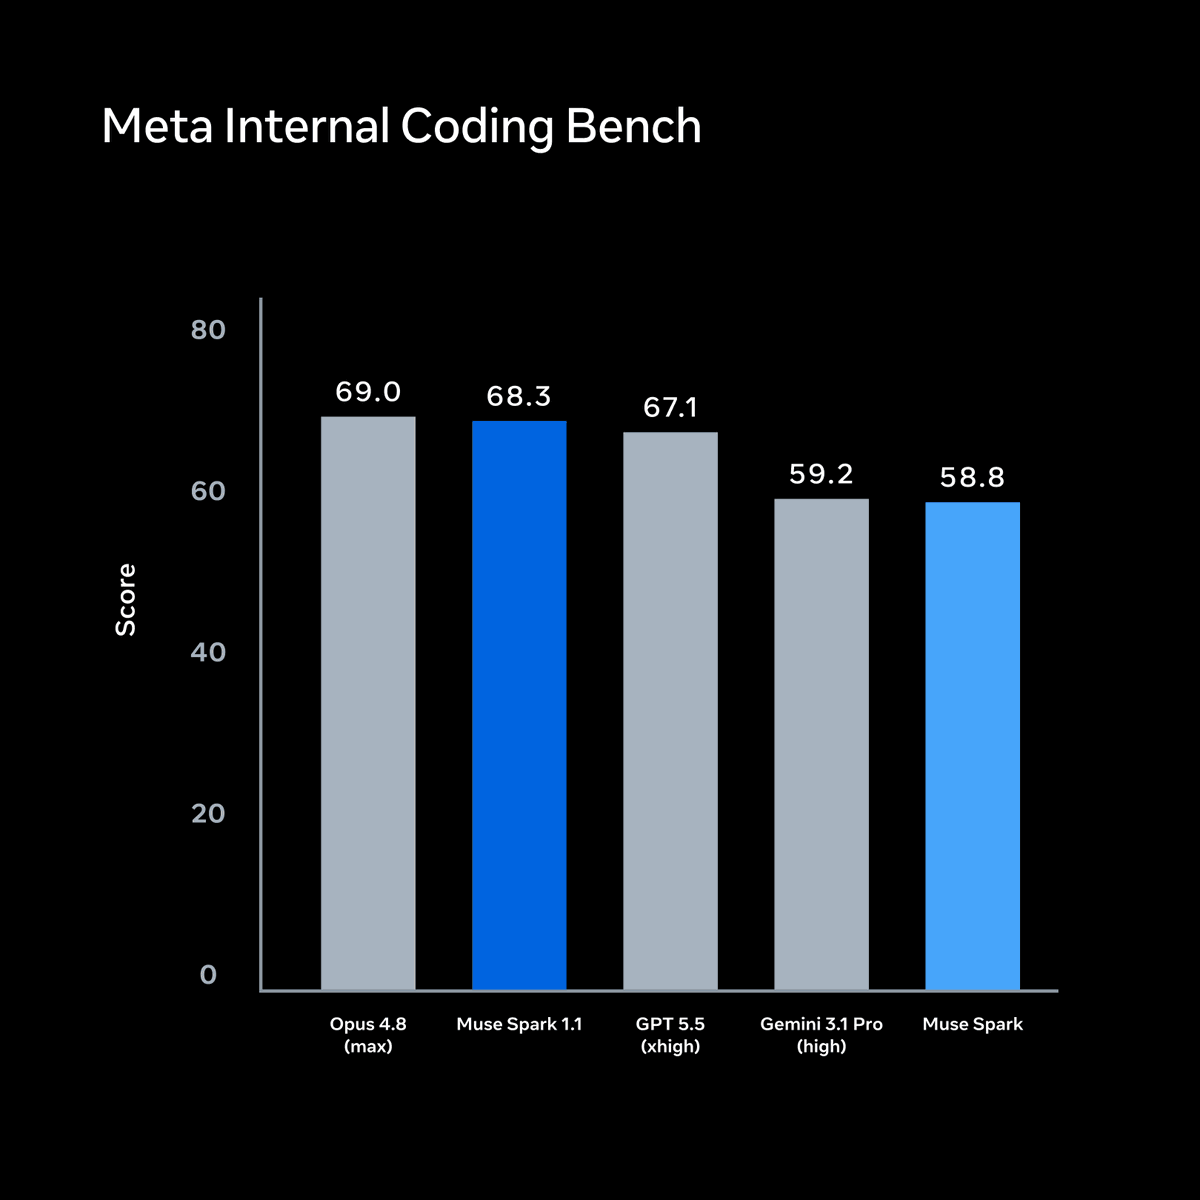
Muse Spark 1.1 is used across Meta in coding and research workflows, scoring competitively with leading models on Meta's internal coding benchmark. Our researchers are now automating model development and evaluation tasks by leveraging Muse Spark 1.1 in their workflows. https://t.co/ME28wXs9Ut
 Fei Xia@xf1280 · 13 Apr
Muse Spark is agentic, which means you can ask it to leverage different test-compute scaling methods to improve quality. Here I ask the model to use parallel subagents to do counting and the results are greatly improved! https://t.co/W5KKfSN6JW https://t.co/nG1857hbF6

 Tim Jayas@TimJayas · 12 Oct
muse-wonder just got better (before/after) after @alexandr_wang acknowledged there were bunch of bugs, there's been a noticeable improvement with muse-wonder both outputs are from the same prompt, one taken directly after the model launch and the one after the fix

 pilvar (Philippe Dourassov)@pilvar222 · 3 Sept
We ran Muse Spark 1.3 on our Cybersecurity benchmark, and it's actually not that good (yet) 😬 - At pass@1, it rediscovers an average of 19/32 CVEs. In comparison, Grok 4.6 scores 23.3/32 - When pooling the results of 3 runs (pass@3), Muse scores 24/32. DeepSeek V4 Pro gets https://t.co/B1cMKgiX5Q

 Morgan@morganlinton · 21 Sept
Okay, finally finished my Muse Spark 1.3 benchmark. This ended up being the longest-running benchmark I've ever done at @VulcanBench and it definitely looks like Muse has some serious issues at lower effort levels. I was able to run Astra through my v4 eval suite across every https://t.co/47d904IrpR


 チャエン | デジライズ CEO《重要AIニュースを毎日最速で発信⚡️》@masahirochaen · 10 Aug
【速報】Metaが30BのオープンモデルMuse Glimmerを公開。18GBのRAMで動く。 久々のMetaからの本格オープンモデル。 小型なので低スペックのPCでも動かせるAIモデル。 ・Apache 2.0で商用利用可、重みはHugging Faceで公開 ・画像も読めるvisionモデル、100言語超に対応 ・MCP Atlas https://t.co/EsJvNO4hw7

 Alex Volkov@altryne · 9 Sept
Here's my full in depth review of @muse (https://t.co/RcAI2g1Qjm) Meta's new FREE AI agent with it's own browser, computer and connectors to anything from FB marketplace to Apple health! I go into setting it up, have it buy stuff securely with @link, and 3 great usecases that https://t.co/sAe2Oqn6HW

61 public posts describe it. Evals, comparisons and research findings about Muse models. Each card above quotes the poster or condenses their post, and links to the original.
No. Outcomes are what each poster reported. Built with Muse did not verify the savings, bookings or completions. 61 of the 61 posts are in the poster's own words; the rest are condensed summaries with a link back.
0 of these posts come with a prompt you can copy and adapt. Open Try the prompt on a card, paste it into Muse, and replace the bracketed parts with your own details.
Muse is invite only in most places. Built with Muse runs a community pool of invite codes: take one, redeem it in the Muse app, then add your own for the next person.
Outcomes are what the poster reported. Built with Muse did not verify the savings, bookings, or completions. Posts with text_source tweet are the author's own words. Posts with text_source field-guide-summary are condensed from the public post by the EveryAI Muse field guide (snapshot 2026-09-14) and link back to the original. Some entries were first catalogued by shipwithmuse.live. Data updated 2026-10-09.